

In this tutorial, we will walk you through how to match document data to Excel using Lido. Simply follow the steps below.
The steps below use a bank statement matched against a ledger as the example, but the same process works for invoices matched against a PO list, receipts matched against expense reports, and other documents.
Before you start, make sure you have the documents you want to match saved as PDFs, images, or scanned copies. Your Excel reference file (such as your ledger, PO list, or vendor list) should be saved in Google Drive, OneDrive, or SharePoint.
If you don't have a Lido account yet, you can create one for free here.
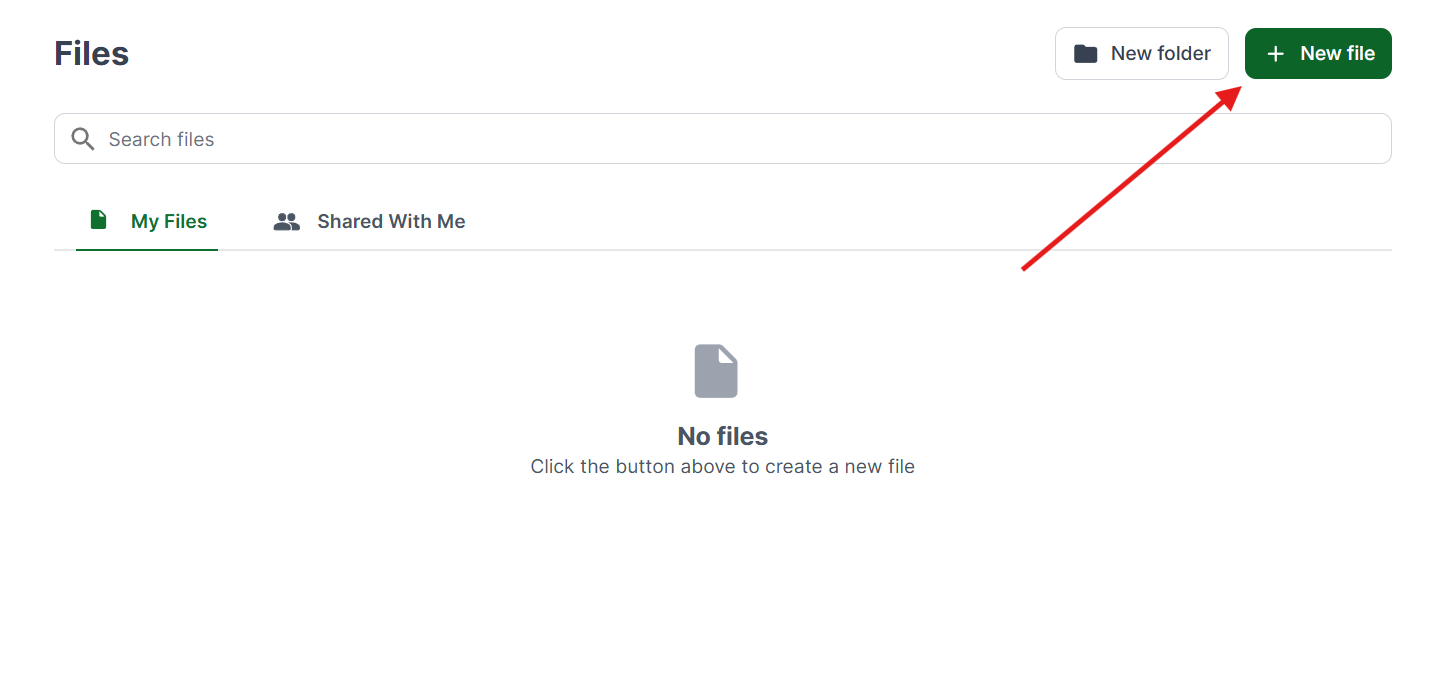
Once you're logged in, create a New File.
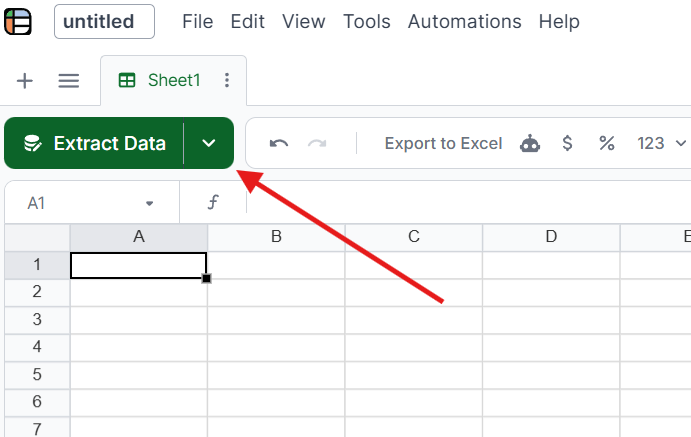
Select the Extract Data button at the top of the sheet.
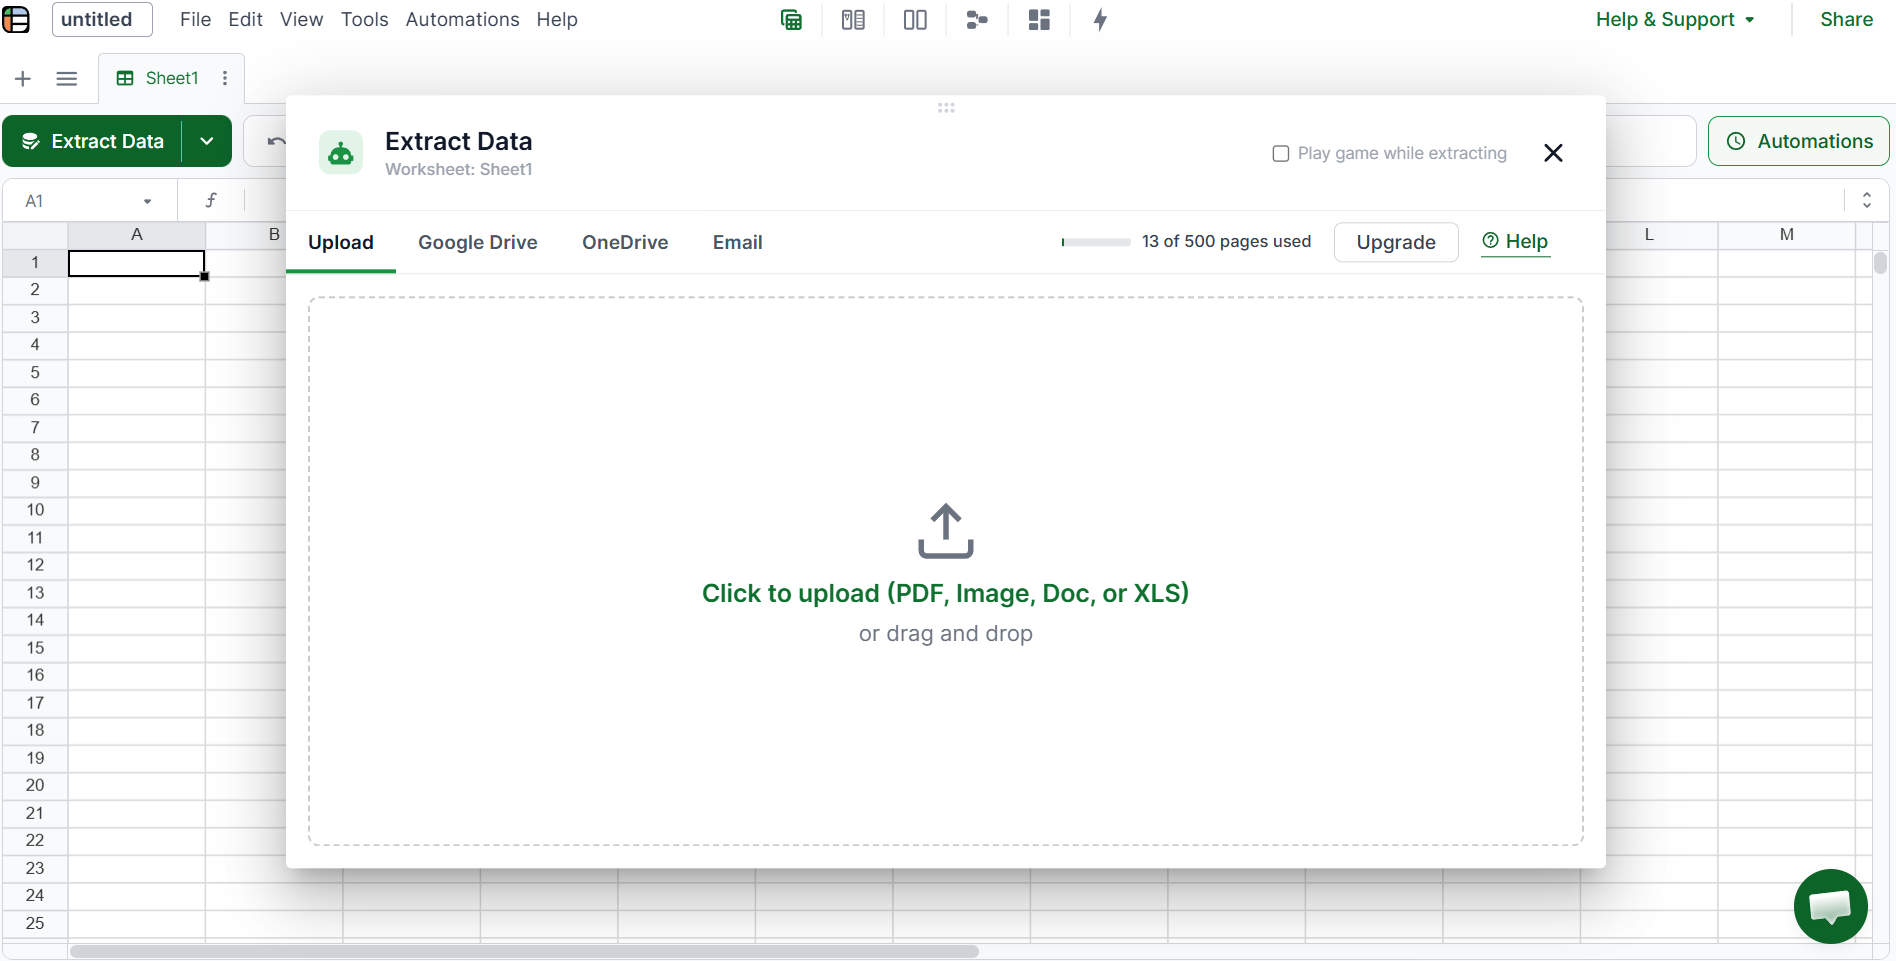
Upload your files by dragging and dropping them into Lido, or click to browse. Lido will automatically analyze each file for you.
For the purpose of this tutorial, we will be using a sample bank statement that we want to match against a ledger in Excel.
Enter the columns you want to pull from your documents. For a bank statement, that would be Date, Amount, and Description. For an invoice, it might be Invoice Number, Vendor, PO Number, and Total.
To see the match results in your output, add extra columns such as Matched Ledger Entry or Match Status.
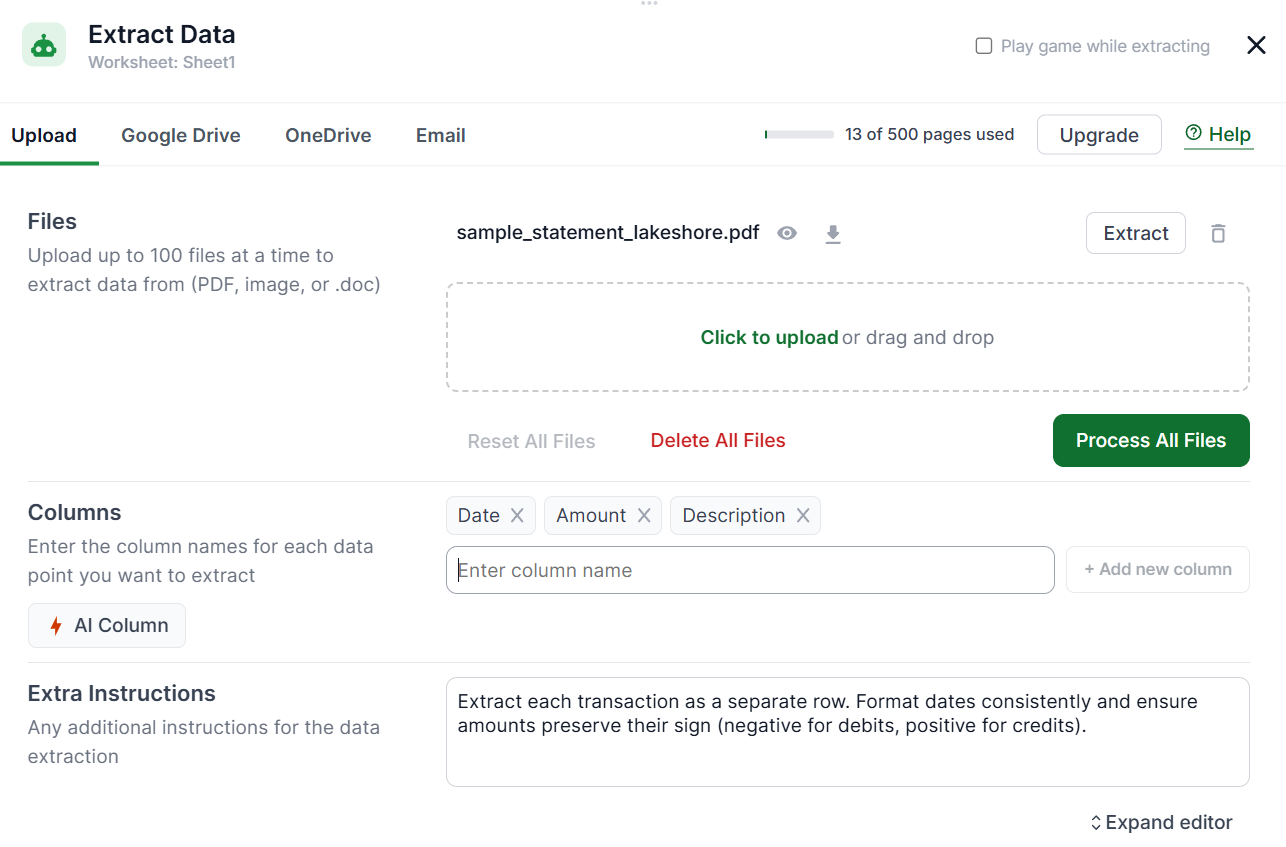
In the Extra Instructions section, click + Context Doc, select where your Excel file is saved, and upload it. This gives Lido your existing records to match against.
Then add a short instruction explaining how to match, such as "Match each transaction to the ledger entry with the same date and amount, and mark any transaction without a match as Unmatched." Once done, click Process All Files.
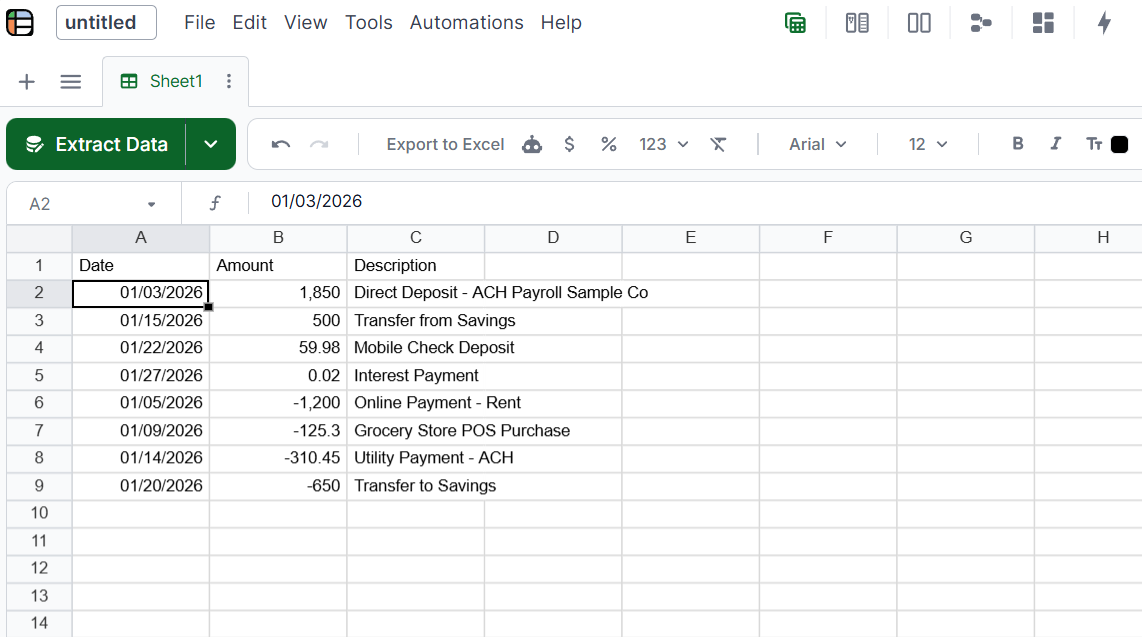
Review the extracted and matched data to make sure everything looks correct. Focus on any rows marked as unmatched, since these are the items that need a closer look.
From here, you can edit and format the data however you want, just like in any spreadsheet.
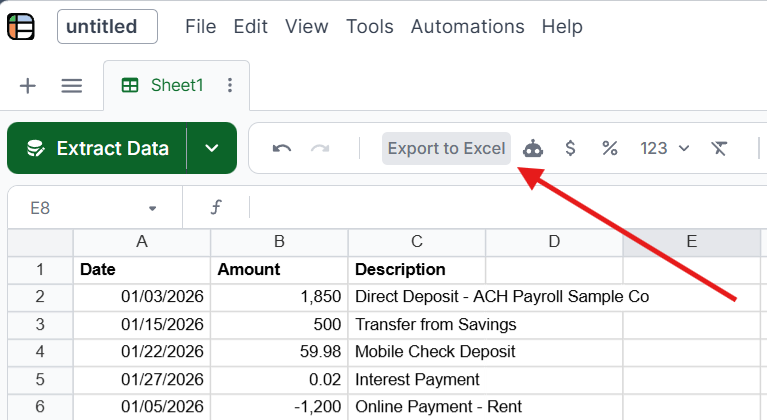
Once you're done, click Export to Excel to download your matched data as a spreadsheet file.
If you'd rather not use an AI tool, there are a few other options. Here's how they compare:
Manual matching: Open each document next to your spreadsheet and compare the values by hand. This works for a few documents a week but gets slow and error-prone as volume grows. Some teams speed this up with tables copied from PDF into Google Sheets, but checking each row still takes time.
VLOOKUP or INDEX-MATCH: Type the document data into Excel, then use lookup formulas to find the matching rows in your reference table. The formulas handle the matching, but someone still has to enter the data, and small differences like "Acme Corp" vs. "Acme Corporation" make lookups fail. You can save some typing by moving a PDF table into Excel first, but name mismatches remain.
Excel add-ins like DataSnipper: Link values in a PDF to cells in your workbook so reviewers can trace each number back to its source. This is useful for audit samples, but each link is created by hand, so it doesn't scale to hundreds of documents.
Most matching work falls into one of these categories:
Invoice to PO matching: Confirm every invoice has a matching purchase order and that the billed amount doesn't exceed what was approved.
Bank reconciliation: Match each transaction on a bank statement to its entry in the general ledger, usually by date and amount.
Audit vouching: Trace a sample of transactions in a workpaper back to the source documents that support them.
Now that you know how to match document data to Excel, you can spend less time on manual lookups and more time resolving the exceptions that matter.
The most effective approach is to automate both extraction and matching in a single pipeline. First, use AI-powered extraction to pull structured data from your source documents (invoices, statements, receipts, contracts) without manual data entry. Then, match the extracted data against your reference spreadsheet using a combination of exact matching on numeric fields (amounts, dates, PO numbers) and fuzzy matching on text fields (vendor names, descriptions). Tools like Lido handle both steps: you upload documents and a reference file, and Lido returns matched rows with exceptions flagged. This eliminates the manual extraction bottleneck and reduces false exceptions caused by data entry errors or string mismatches in lookup formulas.
Yes. AI extraction reads the invoice to identify the PO number, vendor name, line items, and amounts, then matches each field against your PO list. The matching handles common complications like partial PO references (an invoice that lists only the last six digits of a 10-digit PO number), vendor name variations between the invoice and your vendor master, and multi-line invoices where individual line amounts need to match against PO line items rather than just the invoice total. Lido performs this matching automatically and flags any invoices where the PO number is missing, the amount exceeds the PO by more than your defined tolerance, or the vendor name cannot be resolved against your records.
Fuzzy matching compares two text strings and determines whether they refer to the same entity despite surface-level differences. When Lido extracts a vendor name like "Acme Corp" from an invoice, it compares that string against every entry in your vendor master file. The comparison accounts for common variations: abbreviations (Corp vs. Corporation), punctuation (Inc. vs Inc), word order (Johnson Controls vs. Controls, Johnson), and minor misspellings. The algorithm assigns a confidence score to each potential match and selects the highest-scoring candidate above a threshold. This means "iTool," "iTool Co.," and "I-Tool Company" all resolve to the same canonical vendor entry without any manual cleanup. If no match exceeds the confidence threshold, the item is flagged as unmatched for manual review rather than being silently assigned an incorrect match.
Format variation is one of the primary reasons template-based OCR tools fail at scale. Every vendor has a different invoice layout: different placement of the invoice number, different line item table structures, different ways of presenting tax and totals. Lido uses AI-based extraction that reads documents the way a human would, understanding the semantic meaning of each field regardless of where it appears on the page. Whether the invoice number is in the top-right corner, embedded in a header table, or buried in the footer, Lido identifies and extracts it. You do not need to create or maintain templates for each vendor format. A batch of 200 invoices from 50 different vendors processes in the same run with the same extraction configuration.
Accuracy depends on both the extraction quality and the matching logic. On the extraction side, modern AI-based tools achieve 95 to 99 percent field-level accuracy on clearly printed documents and 90 to 95 percent on lower-quality scans. On the matching side, exact-match fields like invoice numbers and amounts are either correct or flagged. There is no partial match. Fuzzy-match fields like vendor names typically resolve correctly when the reference list is thorough and the name variation is within normal bounds (abbreviations, punctuation differences, minor misspellings). The practical result is that most teams see 85 to 95 percent of documents matched automatically on the first pass, with the remaining 5 to 15 percent flagged for manual review. Those flagged items are real exceptions (missing POs, new vendors not yet in the master file, or amount discrepancies that require investigation) rather than false positives caused by data entry errors.


