

The best way to extract data from any PDF is with an AI extraction tool like Lido. Lido reads digital and scanned PDFs of any layout, pulls out the fields you need, and turns them into clean spreadsheet data you can export to Excel.
In this tutorial, we will walk you through how to extract data from any PDF using Lido. Simply follow the steps below.
Before you start, make sure you have the PDF you want to extract data from saved on your computer.
If you don't have a Lido account yet, you can create one for free here.
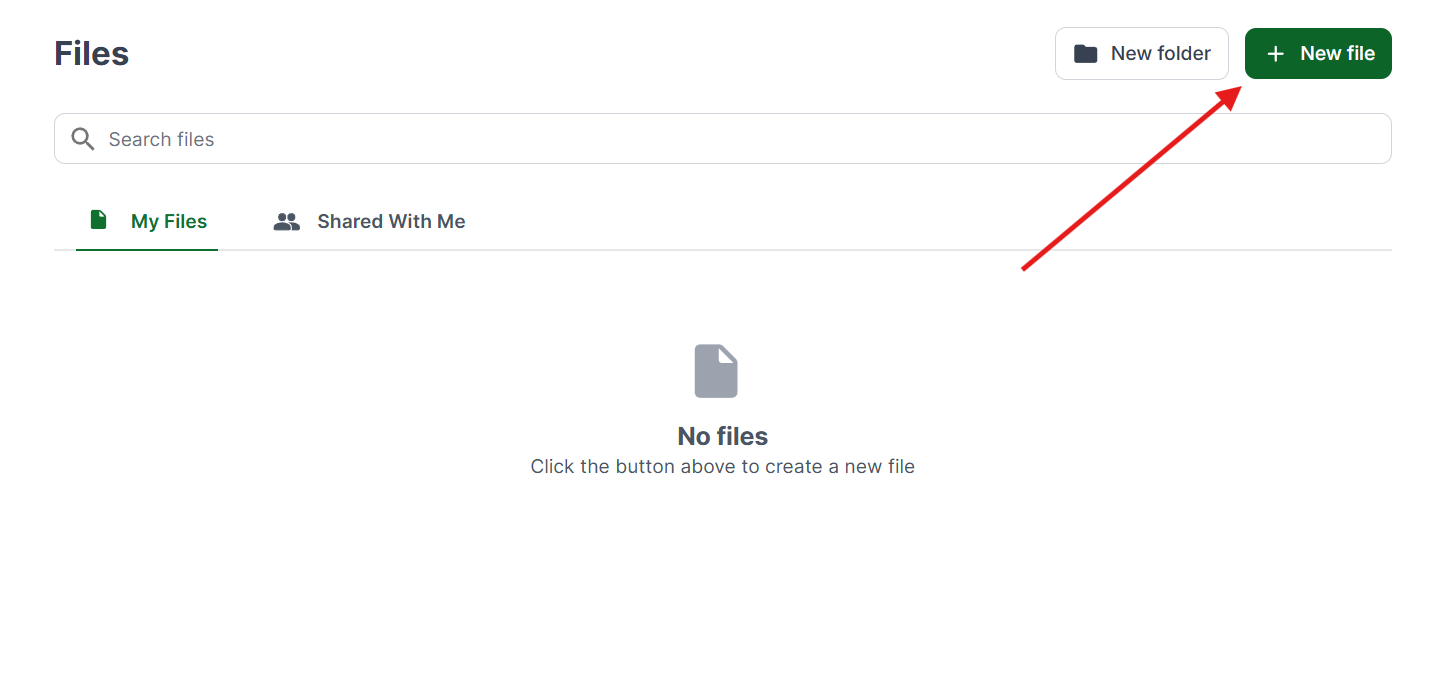
Once you're logged in, create a New File.
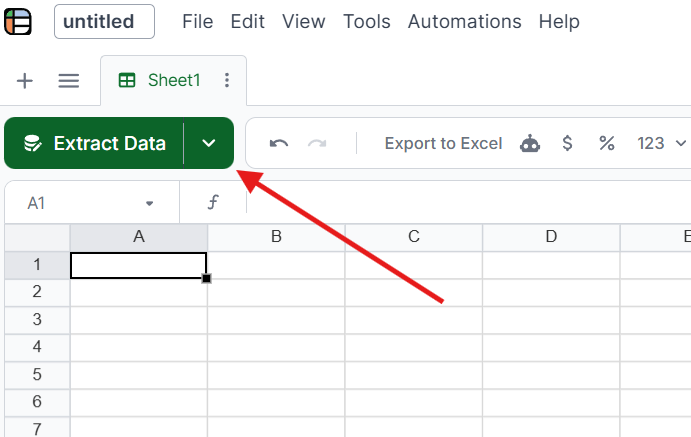
Select the Extract Data button at the top of the sheet.
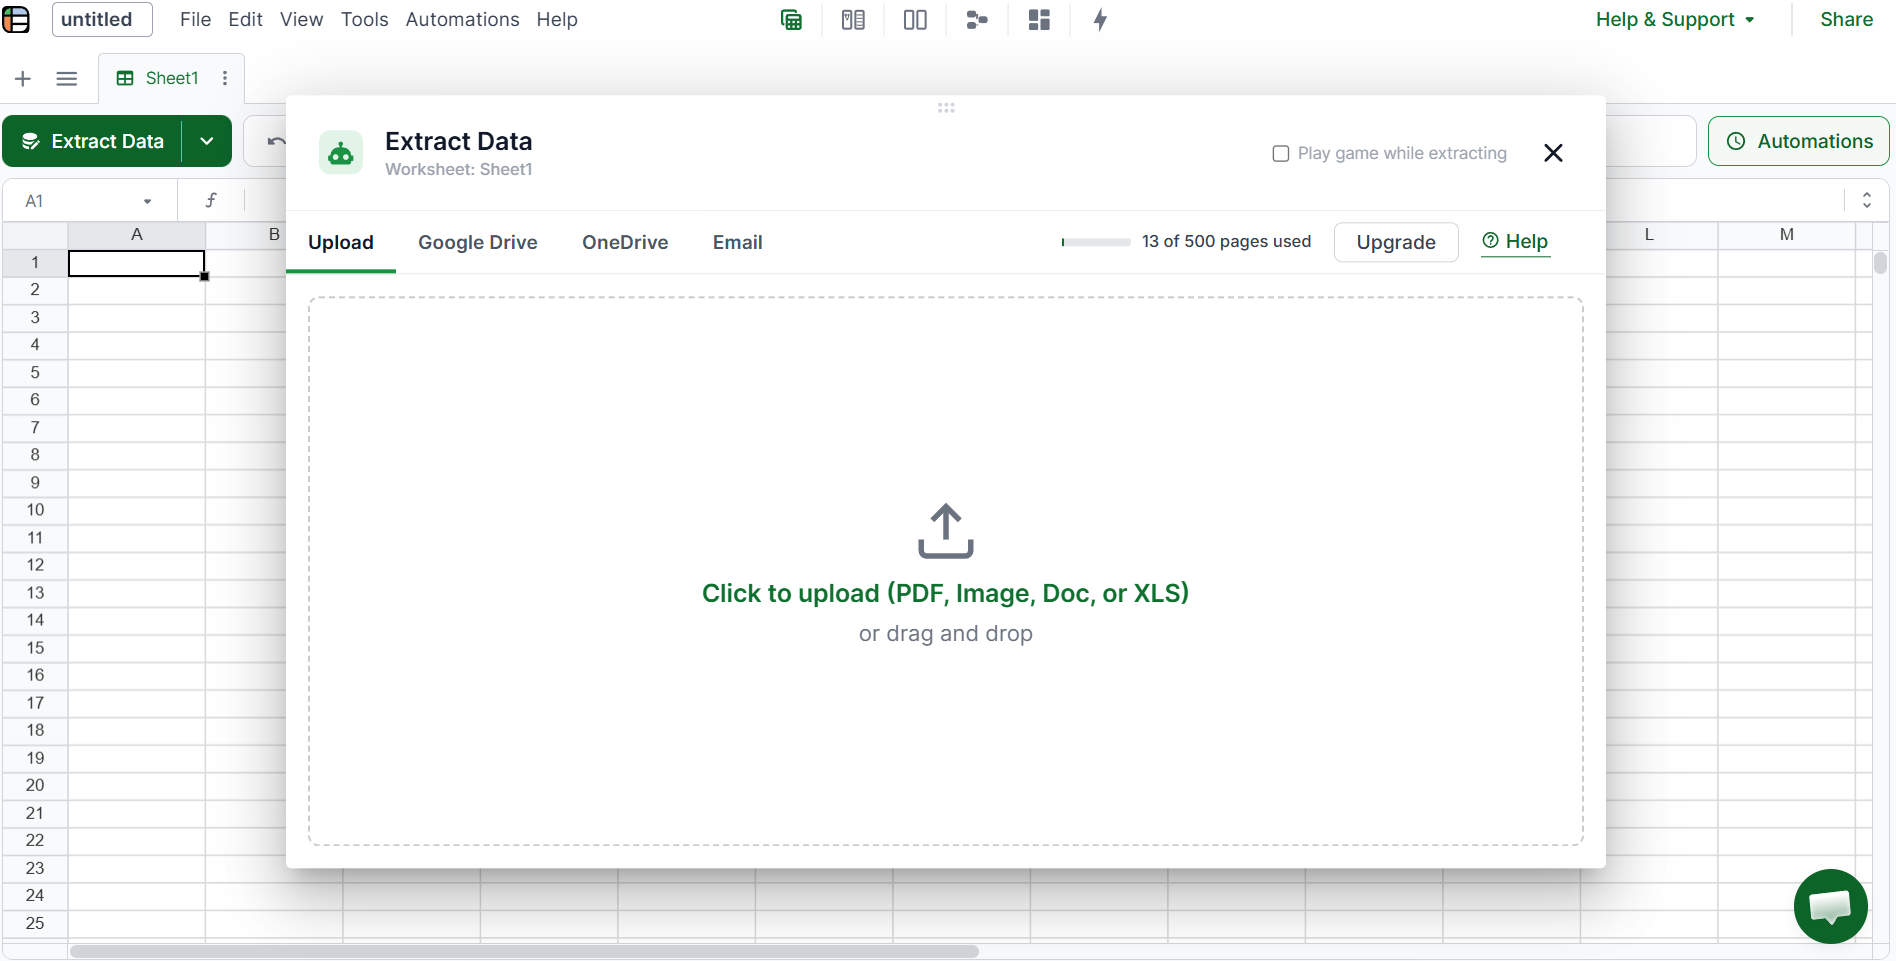
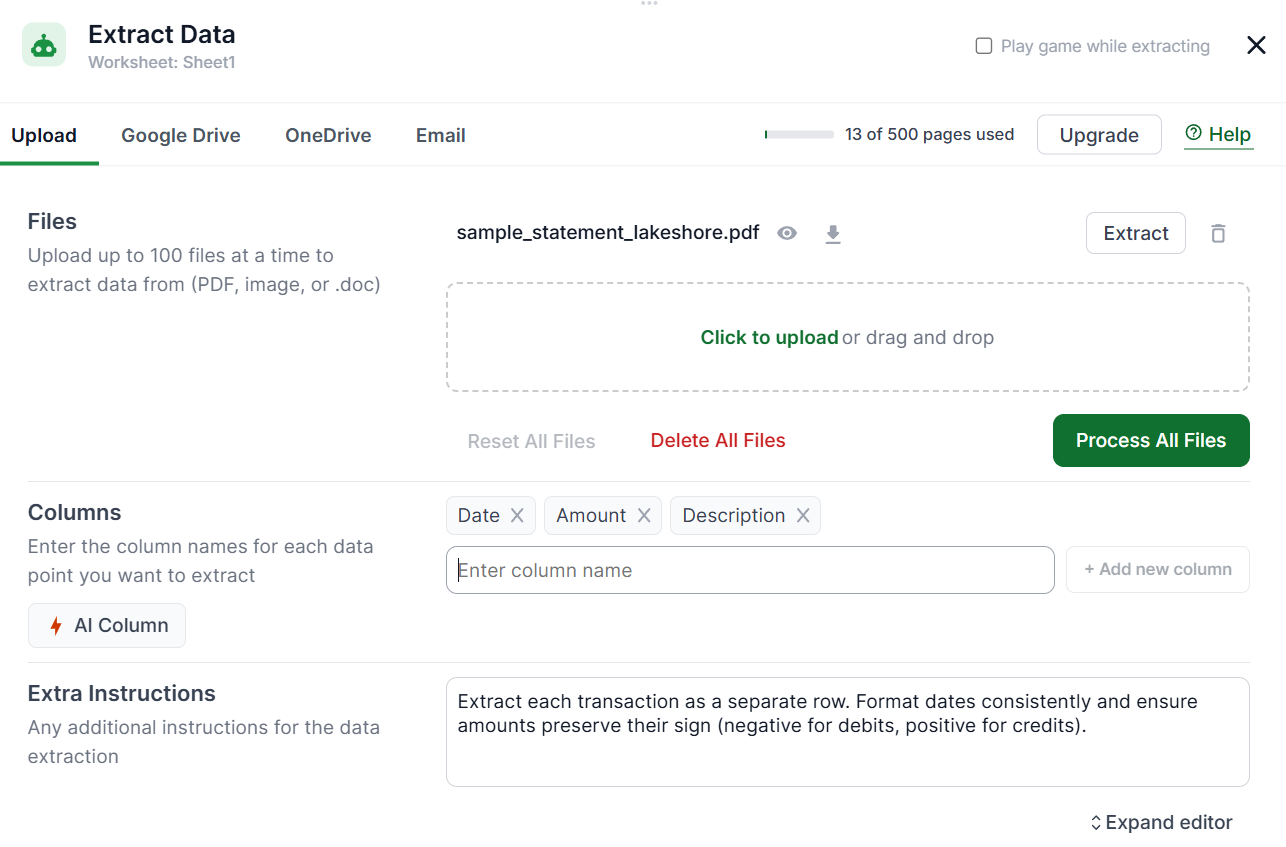
Upload your file by dragging and dropping it into Lido, or click to browse. Lido will automatically analyze the file for you.
For the purpose of this tutorial, we will be using a sample bank statement. The same steps work for invoices, receipts, purchase orders, forms, and any other PDF. Finance teams follow the same process when capturing financial data from statements, invoices, and receipts.
Enter a column name for each piece of data you want to pull from your PDF. For a bank statement, that would be Date, Amount, and Description. For an invoice, it might be Invoice Number, Vendor Name, and Total.
You can also add extra instructions if you'd like (this is optional), such as extracting each transaction or line item as its own row. Once done, click Process All Files.
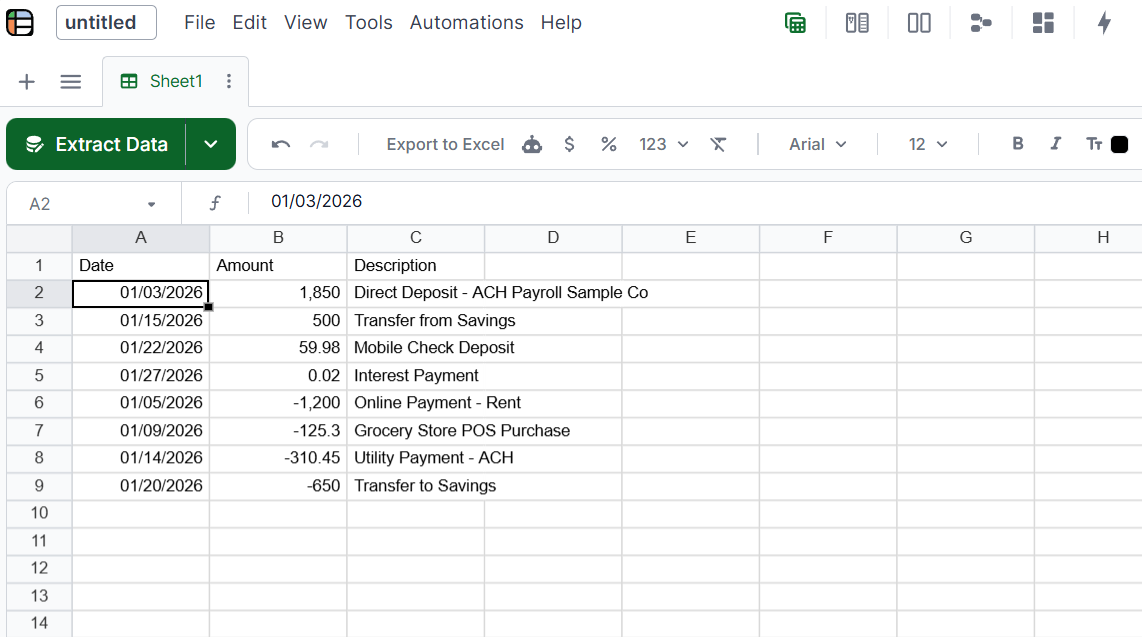
Review the extracted data to make sure it's in the format you need. You can edit cells, adjust column widths, or reorganize the data to suit your workflow.
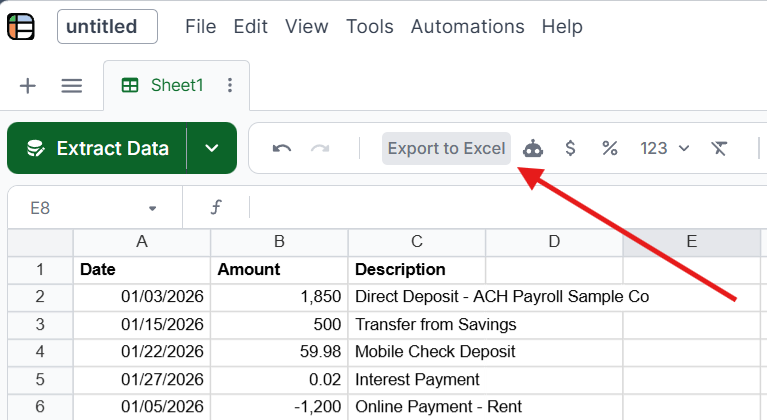
Once you're done, click Export to Excel to download your data as a spreadsheet file.
If you only need data from one simple PDF, these options may also work:
Copy and paste: Highlight the text in your PDF reader and paste it into a spreadsheet. It's free and fast, but it only works on digital PDFs and usually breaks tables into one column. Scanned PDFs need a different approach, such as using OCR for data entry, because they have no text to highlight.
Adobe Acrobat Pro: Use Export PDF to save the file as an Excel spreadsheet. It keeps simple tables in place, but it requires a paid subscription and copies the page layout rather than pulling out specific fields.
Tabula and Camelot: Free, open-source tools that extract tables from digital PDFs. They work well for developers, but they can't read scanned PDFs.
Free online converters: Sites like Smallpdf convert a PDF to Excel in a few clicks. They're fine for one-off files, but tables often break, and your document is uploaded to a third-party server.
For detailed tool comparisons, see best PDF data extraction tools, best PDF to Excel converters, and best PDF to CSV converters.
Now that you know how to extract data from any PDF, you can turn your documents into clean spreadsheet data in minutes.
The best way is to use an AI extraction tool like Lido. Upload your PDF, enter the columns you need, and Lido pulls the data into a spreadsheet with 99.9% accuracy. It works on invoices, bank statements, forms, and any other PDF without templates.
Yes, but only with a tool that includes OCR (software that reads text from images). Lido has built-in OCR that reads scanned and photographed PDFs. Free tools like Tabula, Camelot, and most online converters cannot read scanned documents.
Upload your PDF to Lido, enter the columns you want to extract, and click Process All Files. Review the data, then click Export to Excel to download it as a spreadsheet.
Yes. Tabula and Camelot are free for tables in digital PDFs, and online tools like Smallpdf offer limited free conversions. For scanned PDFs or business documents, Lido offers 50 free pages so you can test it on your own files.


